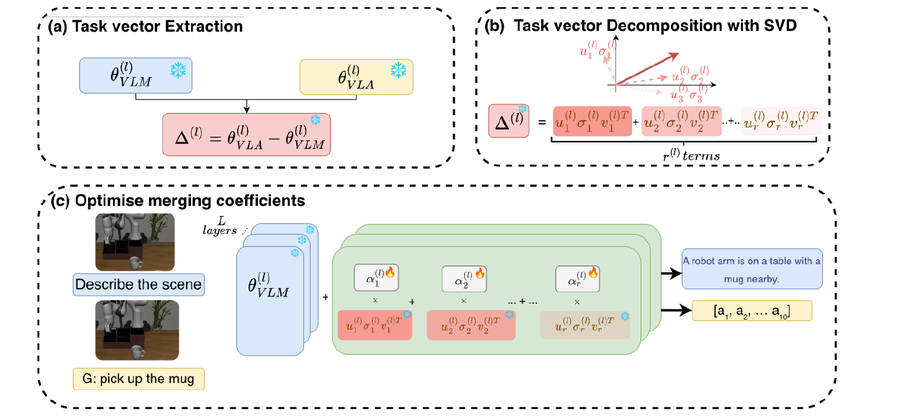
Vision-Language-Action models (VLAs) are obtained by fine-tuning pre-trained Vision-Language Models (VLMs) on robot demonstration data, enabling action prediction from visual observations and language instructions. However, this fine-tuning induces catastrophic forgetting, substantially degrading the semantic and visual grounding capabilities of the original VLM. We address this by merging the parameters of a VLM and its VLA derivative without retraining either model. Concretely, we extract the task vector, the difference between VLA and VLM weights, and decompose it via Singular Value Decomposition. For each component, we learn a scalar mixing coefficient controlling how much of the VLA adaptation is retained, optimised to jointly preserve action prediction and vision-language capabilities. Experiments show that our merged model performs well on both axes simultaneously, consistently outperforming established merging baselines.
@inproceedings{aissi2027vlamerge,title={Bring Back Language to Actions: Restoring VLM Capabilities in VLA Models via Parameter Merging},author={Aissi, Mohamed Salim and Sigaud, Olivier and Soulier, Laure and Thome, Nicolas},booktitle={Proceedings of the Conference of the European Chapter of the Association for Computational Linguistics (EACL), Main Conference},year={2027},note={Also accepted at the NeurIPS 2026 Workshop RoboPAD (Paris). arXiv coming soon}}
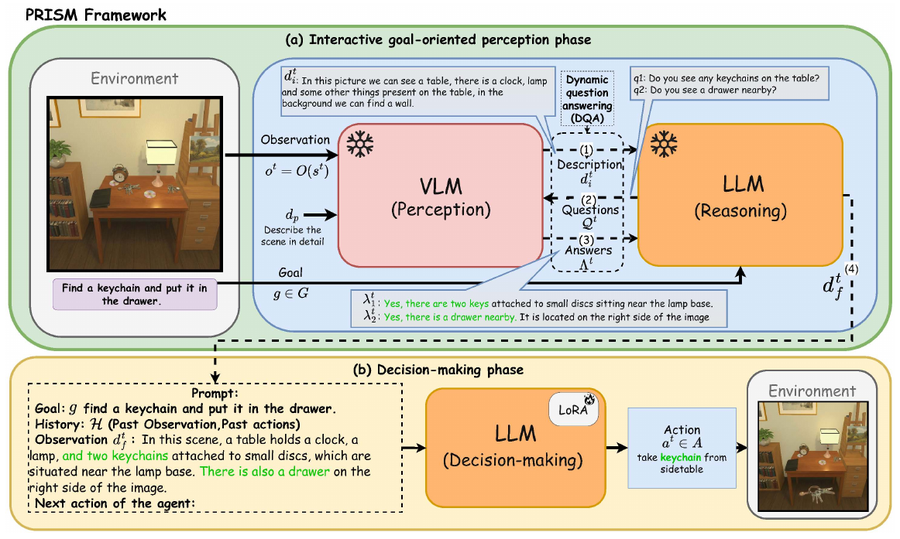
Scaling LLM-based embodied agents from text-only environments to complex multimodal settings remains a major challenge. Recent work identifies a perception-reasoning-decision gap in standalone Vision-Language Models (VLMs), which often overlook task-critical information. In this paper, we introduce PRISM, a framework that tightly couples perception (VLM) and decision (LLM) through a dynamic question-answer (DQA) pipeline. Instead of passively accepting the VLM’s description, the LLM critiques it, probes the VLM with goal-oriented questions, and synthesizes a compact image description. This closed-loop interaction yields a sharp, task-driven understanding of the scene. We evaluate PRISM on the ALFWorld and Room-to-Room (R2R) benchmarks. We show that: (1) PRISM significantly outperforms state-of-the-art image-based models, (2) our Interactive goal-oriented perception pipeline yields systematic and substantial gains, and (3) PRISM is fully automatic, eliminating the need for handcrafted questions or answers.
@inproceedings{aissi2026prism,title={PRISM: Perception Reasoning Interleaved for Sequential Decision Making},author={Aissi, Mohamed Salim and Grislain, Clemence and Romac, Clement and Soulier, Laure and Chetouani, Mohamed and Sigaud, Olivier and Thome, Nicolas},booktitle={International Conference on Machine Learning (ICML)},year={2026},}
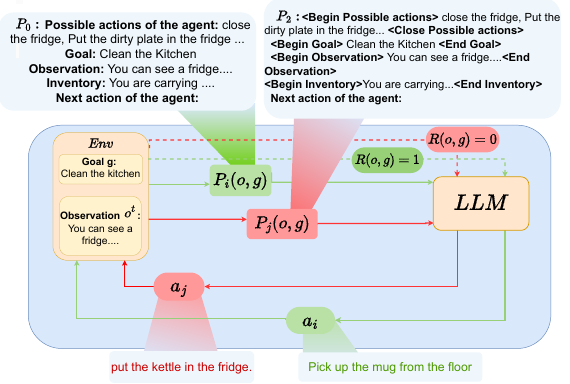
@inproceedings{aissi2025rlprompt,title={Reinforcement Learning for Aligning Large Language Models Agents with Interactive Environments: Quantifying and Mitigating Prompt Overfitting},author={Aissi, Mohamed Salim and Romac, Clement and Carta, Thomas and Lamprier, Sylvain and Oudeyer, Pierre-Yves and Sigaud, Olivier and Soulier, Laure and Thome, Nicolas},booktitle={Findings of the Association for Computational Linguistics: NAACL 2025},pages={7045--7061},year={2025}}
Preprint
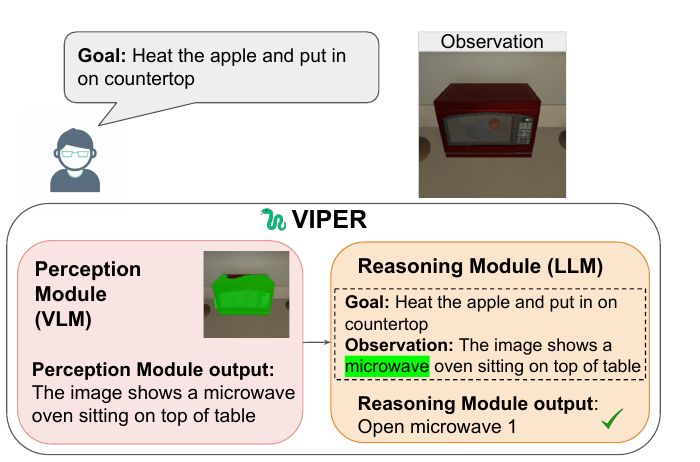
VIPER: Visual Perception and Explainable Reasoning for Sequential Decision-Making
Mohamed Salim Aissi, Clemence Grislain, Mohamed Chetouani, and 3 more authors
@misc{aissi2025viper,title={VIPER: Visual Perception and Explainable Reasoning for Sequential Decision-Making},author={Aissi, Mohamed Salim and Grislain, Clemence and Chetouani, Mohamed and Sigaud, Olivier and Soulier, Laure and Thome, Nicolas},year={2025}}
TALN
Apprentissage par renforcement pour l’alignement des agents LLMs avec des environnements interactifs : quantification et réduction du surapprentissage aux prompts
Mohamed Salim Aissi, Clement Romac, Thomas Carta, and 5 more authors
@inproceedings{aissi2025taln,title={Apprentissage par renforcement pour l'alignement des agents LLMs avec des environnements interactifs : quantification et r{\'e}duction du surapprentissage aux prompts},author={Aissi, Mohamed Salim and Romac, Clement and Carta, Thomas and Lamprier, Sylvain and Oudeyer, Pierre-Yves and Sigaud, Olivier and Soulier, Laure and Thome, Nicolas},booktitle={Actes de TALN 2025},pages={6--7},year={2025}}
 Apprentissage par renforcement pour l’alignement des agents LLMs avec des environnements interactifs : quantification et réduction du surapprentissage aux promptsIn Actes de TALN 2025, 2025